Building a Production Extraction Pipeline with Confidence Scoring
Build an enterprise extraction pipeline that assesses its own confidence, flags ambiguous edge cases, and intelligently routes requests between automated processing and human review.
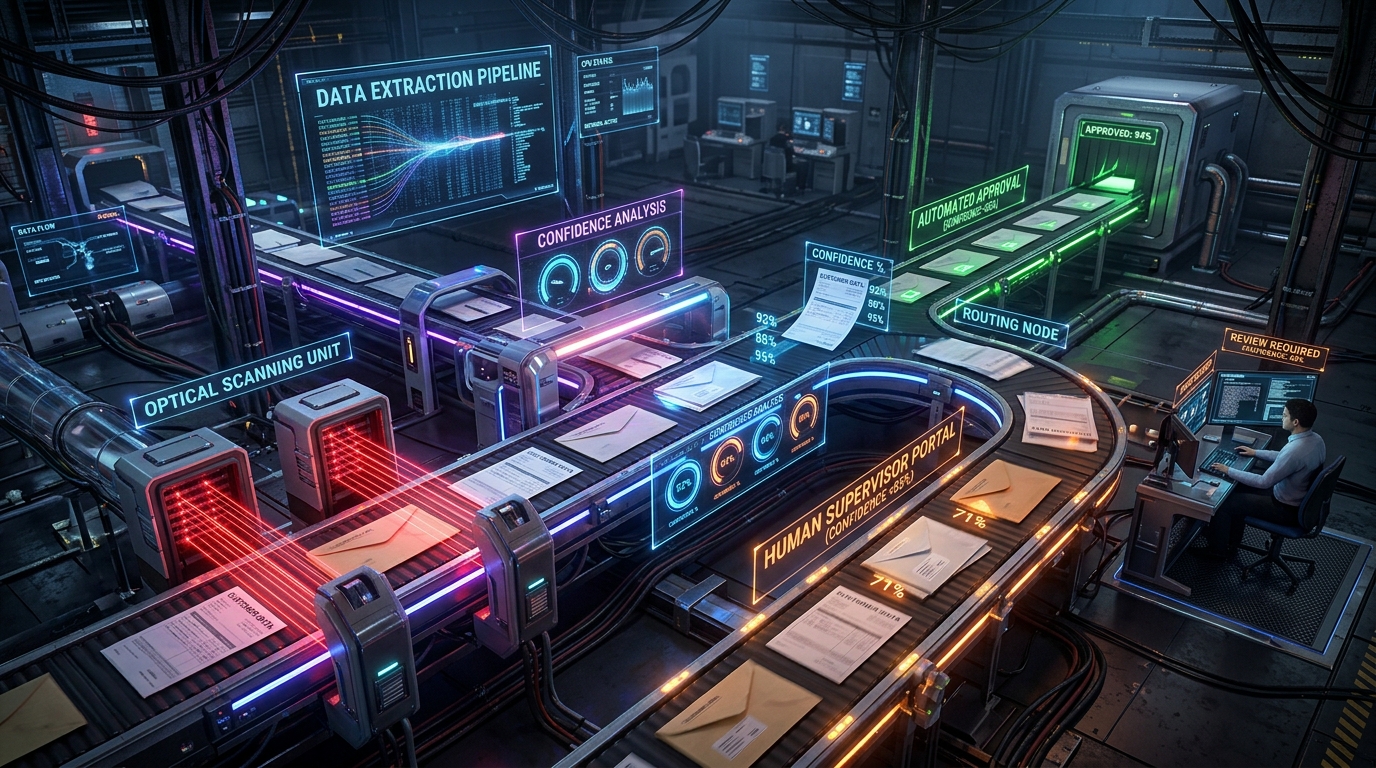
TL;DR: Basic extraction only extracts fields from text. A production extraction pipeline also generates meta-information about its own extraction — computing confidence scores, identifying missing information, and flagging contradictions. This allows you to build safe Human-in-the-Loop (HITL) triage systems.
📦 Interactive Notebook: Test and run this code live on GitHub:
08_extraction_pipeline.ipynbin the ai-architect-foundation-gemini repository.
What You'll Learn
How to design extraction schemas that output self-confidence metadata, how to detect contradictory customer claims, and how to implement deterministic business logic that routes high-confidence items to automation and low-confidence items to human review.
The Core Idea: Extraction Needs Self-Aware Metadata
In real-world customer support and document processing:
- Some messages are crystal clear ("I want to return order ORD-1001 because the shoes are size 9 instead of 10").
- Other messages are ambiguous or contradictory ("The watch arrived completely broken but works perfectly, I need a refund today").
If your system processes everything automatically, contradictory or high-risk cases cause costly operational errors. If your system routes everything to humans, you gain zero automation benefits.
The Solution: Have the model extract the core payload plus metadata:
confidence: A float score (0.0 to 1.0) of certainty.human_review_required: A boolean flag for policy contradictions or ambiguities.human_review_reason: An explicit justification for why human intervention is recommended.
The Production Extraction Schema
from google import genai
from google.genai import types

client = genai.Client()
model = "gemini-2.5-flash"

extract_tool = types.FunctionDeclaration(
    name="extract_return_request",
    description="Extract a structured return request from a customer message.",
    parameters=types.Schema(
        type="OBJECT",
        properties={
            "order_id": types.Schema(
                type="STRING",
                description="The order ID provided by the customer, or null if missing.",
                nullable=True
            ),
            "item": types.Schema(
                type="STRING",
                description="The item the customer wants to return, or null if missing.",
                nullable=True
            ),
            "reason": types.Schema(
                type="STRING",
                enum=["damaged_item", "wrong_item", "changed_mind", "billing_dispute", "policy_exception", "unclear", "other"]
            ),
            "reason_details": types.Schema(
                type="STRING",
                description="Additional details when reason is other or unclear.",
                nullable=True
            ),
            "desired_action": types.Schema(
                type="STRING",
                enum=["return", "refund", "exchange", "replacement", "unclear"]
            ),
            "evidence_provided": types.Schema(
                type="BOOLEAN",
                description="Whether the customer provided evidence such as a photo or attachment."
            ),
            "urgency": types.Schema(
                type="STRING",
                enum=["low", "normal", "high"]
            ),
            "missing_information": types.Schema(
                type="ARRAY",
                items=types.Schema(type="STRING")
            ),
            "confidence": types.Schema(
                type="NUMBER",
                description="Confidence score from 0 to 1 for the extraction."
            ),
            "human_review_required": types.Schema(type="BOOLEAN"),
            "human_review_reason": types.Schema(
                type="STRING",
                nullable=True
            )
        },
        required=[
            "order_id", "item", "reason", "reason_details",
            "desired_action", "evidence_provided", "urgency",
            "missing_information", "confidence",
            "human_review_required", "human_review_reason"
        ]
    )
)

tools = [types.Tool(function_declarations=[extract_tool])]
tool_config = types.ToolConfig(
    function_calling_config=types.FunctionCallingConfig(
        mode="ANY",
        allowed_function_names=["extract_return_request"]
    )
)
Testing with an Ambiguous / Contradictory Case
Let's test the pipeline against an ambiguous customer message:
customer_message = "The item works perfectly, but it arrived broken, and I need a replacement today"

response = client.models.generate_content(
    model=model,
    contents=customer_message,
    config=types.GenerateContentConfig(
        tools=tools,
        tool_config=tool_config,
        temperature=0.0
    )
)

fc = response.candidates[0].content.parts[0].function_call
result = dict(fc.args)

import json
print(json.dumps(result, indent=2))
Result Payload
{
  "order_id": null,
  "item": null,
  "reason": "damaged_item",
  "reason_details": "Item arrived broken but works perfectly; needs replacement today.",
  "desired_action": "replacement",
  "evidence_provided": false,
  "urgency": "high",
  "missing_information": [
    "order_id",
    "item"
  ],
  "confidence": 0.9,
  "human_review_required": true,
  "human_review_reason": "Customer needs a replacement urgently today."
}
Building the Deterministic Routing Layer
The model provides structured metadata, but the deterministic Python layer makes the final routing decision:
def validate_return_request(data: dict) -> list[str]:
    """Validates missing fields and confidence bounds."""
    errors = []
    if data.get("order_id") is None:
        errors.append("order_id is missing")
    if data.get("item") is None:
        errors.append("item is missing")
    if data.get("confidence", 0.0) < 0.70:
        errors.append("confidence is below review threshold")
    return errors

def route_extracted_claim(claim: dict) -> dict:
    """Evaluates business rules and routes the claim."""
    validation_errors = validate_return_request(claim)

    if validation_errors or claim.get("human_review_required"):
        reasons = list(validation_errors)
        if claim.get("human_review_required"):
            reasons.append(claim.get("human_review_reason") or "Flagged by model for review")

        return {
            "route": "HUMAN_ESCALATION_QUEUE",
            "priority": "HIGH" if claim.get("urgency") == "high" else "MEDIUM",
            "escalation_reasons": reasons,
            "payload": claim
        }

    return {
        "route": "AUTO_PROCESSING",
        "payload": claim
    }

decision = route_extracted_claim(result)
print("\nRouting Decision:")
print(json.dumps(decision, indent=2))

# --- Execution Output ---
# Routing Decision:
# {
#   "route": "HUMAN_ESCALATION_QUEUE",
#   "priority": "HIGH",
#   "escalation_reasons": [
#     "order_id is missing",
#     "item is missing",
#     "Customer needs a replacement urgently today."
#   ],
#   "payload": {
#     "order_id": null,
#     "item": null,
#     "reason": "damaged_item",
#     "reason_details": "Item arrived broken but works perfectly; needs replacement today.",
#     "desired_action": "replacement",
#     "evidence_provided": false,
#     "urgency": "high",
#     "missing_information": [
#       "order_id",
#       "item"
#     ],
#     "confidence": 0.9,
#     "human_review_required": true,
#     "human_review_reason": "Customer needs a replacement urgently today."
#   }
# }
Architecture Benefits
| Capability | Business Impact |
|---|---|
| Tunable Confidence Thresholds | Adjust thresholds (e.g. 0.85 to 0.90) during peak sales seasons to be more conservative. |
| Auditability | Every human escalation includes the model's exact reason, saving human triage time. |
| Fail-Safe Operation | Ambiguous edge cases are never silently dropped or misprocessed. |
Key Takeaways
- Extract Metadata Alongside Data: Always prompt models to report confidence and edge-case flags.
- Deterministic Routing Rules: Keep routing thresholds and compliance checks in Python code, not in the prompt.
- Streamline Human Triage: Provide human operators with structured summaries and model reasoning.
What's Next
In Part 9: Building the Agentic Loop: Autonomous Multi-Step Reasoning, we transition from single-step extractions to multi-step autonomous agent loops.